Guide · AI traffic
The AI Crawler List: Major Bots and What They Do
GPTBot, ClaudeBot, OAI-SearchBot, PerplexityBot, Google-Extended and more, grouped by job (answers, search, training), and what blocking each one means.
· 3 min read
AI companies send several different crawlers, and they do different jobs. Blocking "AI" in robots.txt without knowing which is which can remove you from AI answers while doing nothing about training. Here are the main ones, grouped by what they do.
DataFair keeps a public, longer directory of AI crawlers with each bot's user agent and official documentation link.
The three jobs
- 1AnswersA person asked a question, and the assistant opens your page right now
- 2Search indexingPages are indexed so they can be found and cited later
- 3TrainingPages are collected that may be used to train models
The difference matters: answer and search crawlers can send you visitors. Training crawlers don't send anyone.
Answer crawlers (a person is waiting)
| Crawler | Company | What it does |
|---|---|---|
| ChatGPT-User | OpenAI | Opens a page while ChatGPT answers someone |
| Claude-User | Anthropic | Opens a page while Claude answers someone |
| Perplexity-User | Perplexity | Reads a page to cite it in an answer |
| MistralAI-User | Mistral | Opens a page for someone using Le Chat |
| DuckAssistBot | DuckDuckGo | Reads pages for AI-assisted answers |
Search indexing crawlers (cited later)
| Crawler | Company | What it does |
|---|---|---|
| OAI-SearchBot | OpenAI | Indexes pages for ChatGPT search results |
| Claude-SearchBot | Anthropic | Indexes pages for Claude search results |
| PerplexityBot | Perplexity | Indexes pages for Perplexity results |
| Googlebot | Google Search, including AI Overviews | |
| bingbot | Microsoft | Bing and Copilot search |
| Applebot | Apple | Spotlight, Siri and Safari |
Training crawlers
| Crawler | Company | What it does |
|---|---|---|
| GPTBot | OpenAI | Collects pages that may train OpenAI models |
| ClaudeBot | Anthropic | Collects pages that may train Anthropic models |
| Google-Extended | A robots.txt name controlling use of your pages for Gemini (not a separate crawler) | |
| Applebot-Extended | Apple | A robots.txt name controlling use for Apple's models |
| CCBot | Common Crawl | An open web archive widely used for training |
| Bytespider | ByteDance | Collects pages for ByteDance's models |
| meta-externalagent | Meta | Collects pages for Meta's AI |
| Amazonbot | Amazon | Collects pages for Amazon's services and models |
Blocking: what each choice costs
In robots.txt, you can treat each group separately. For example, to allow answers and search but opt out of OpenAI and Anthropic training:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /
Things to know:
- robots.txt is a request, honoured by the major companies' documented crawlers. It isn't enforcement.
- Blocking search crawlers (OAI-SearchBot, PerplexityBot) can remove you from those assistants' answers, and from the visitors they send.
- User agents can be faked. A request that says GPTBot isn't proof it came from OpenAI. Companies publish IP ranges for verification.
How to see which crawlers visit you
Most AI crawlers download HTML and never run JavaScript, so script-based analytics (GA4, Plausible, DataFair's script) don't see them. You need your server or edge to report them.
DataFair counts them with one API call per request from your server or middleware. It keeps crawlers out of your visitor numbers and shows hits by crawler, by day and by page.
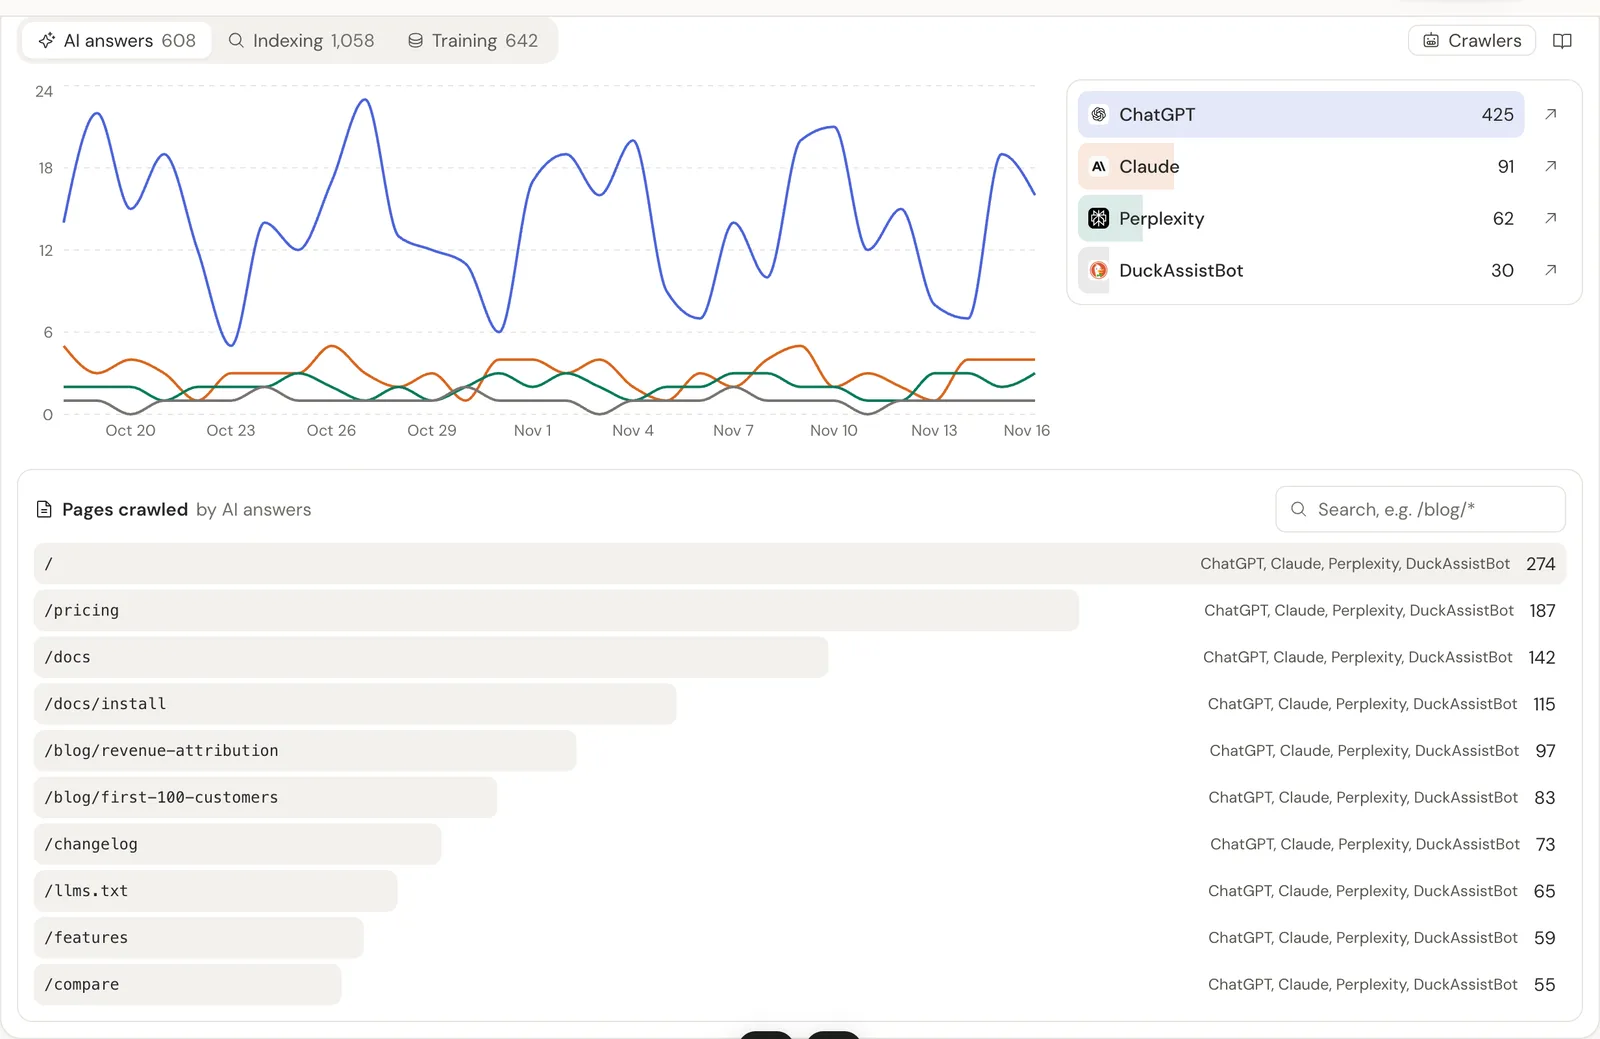
The page view matters most: pages that answer crawlers read often are pages being cited. Pair it with AI referral traffic and revenue from AI visitors to see the whole path.
Related guide: AI traffic analytics: referrals, revenue and crawlers.
Questions
- Does blocking GPTBot remove me from ChatGPT?
- Not from search answers. GPTBot is OpenAI's training crawler. ChatGPT search uses OAI-SearchBot, and ChatGPT-User opens pages when someone asks. Each can be allowed or blocked separately.
- Do AI crawlers count as visitors in analytics?
- Most don't run JavaScript, so script-based tools never count them. DataFair counts them separately and never mixes them with visitors.
- How often does the list change?
- Often. New crawlers appear every few months. DataFair's directory links each crawler to its company's own documentation where one exists.